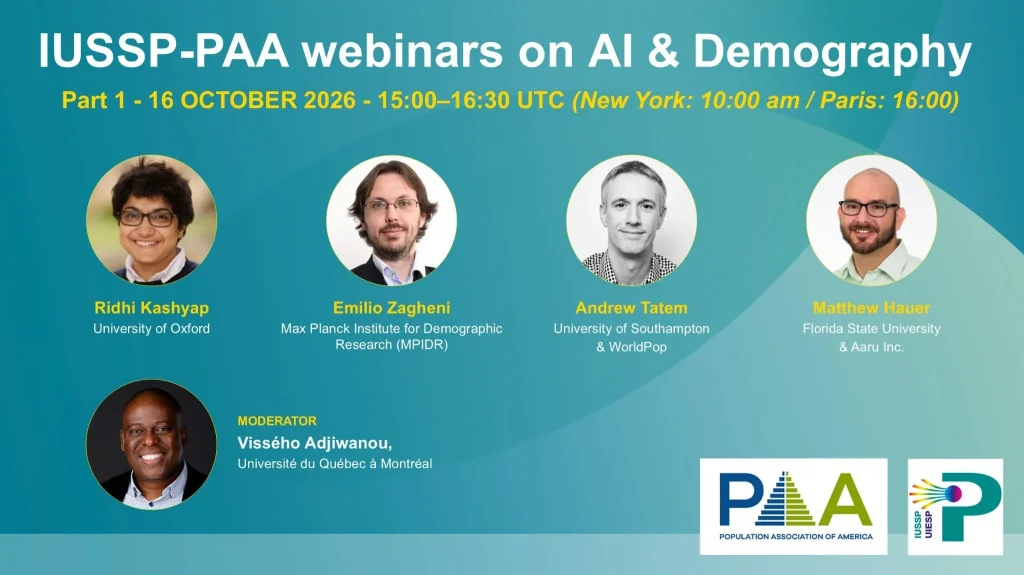
Can artificial intelligence help governments plan services when census data is decades out of date? That question was at the heart of a recent IUSSP-PAA Webinar on AI and Demography, where leading researchers explored both the promise and pitfalls of AI for population science. Among them was WorldPop’s Andrew Tatem, alongside contributors including Emilio Zagheni, Matthew Hauer, Ridhi Kahyap, and moderator Vissého Adjiwanou, discussing the future of AI-enabled demographic research.
In his presentation, Andy Tatem argued that one of AI’s greatest opportunities lies in helping fill critical population data gaps, particularly in countries where censuses are outdated, incomplete or have not taken place for many years. Drawing on WorldPop’s work with governments, ministries of health and international organisations, he showed how satellite imagery, surveys, censuses and mobile phone data can be combined to produce detailed population estimates that support public health and development planning.
These datasets help answer practical questions with real-world consequences: Where should new health facilities be built? How many vaccines are required for a campaign? How many children under five live within a specific catchment area? By combining multiple data sources and AI-driven modelling approaches, WorldPop generate population estimates at neighbourhood scaleto complement traditional demographic data sources and fill gaps.
One particularly striking example was WorldPop’s AI-powered assistant, which allows users to ask population questions in natural language and receive answers derived directly from WorldPop datasets. The tool lowers barriers to accessing demographic information, enabling users without specialist GIS expertise to interact with complex population data in any language they choose.
AI is powerful, but not infallible
Despite showcasing AI’s potential, Prof Tatem delivered a clear warning: demographic research depends on trustworthy data.
He highlighted major differences between satellite-derived building footprint datasets, biases in digital trace data and the risk of models trained primarily on data from high-income countries being applied elsewhere. In some cases, these differences can significantly alter estimates and, consequently, the decisions based upon them.
Tatem also stressed the need for explainability. For national statistics offices and policymakers, producing an accurate answer is only part of the challenge. Equally important is understanding why a model generated that answer and being able to explain it to decision-makers and the public.
His concluding message was perhaps the most important. As AI capabilities continue to advance, the high quality demographic datasets needed to train and validate those systems are, in many places, becoming less available. Prof Tatem noted that around one-third of the world’s population was not counted in the most recent census round, creating growing challenges for evidence-based planning.
Key questions from participants
Prof Tatem explained that validation depends on the intended use of the estimates. WorldPop works with national statistics offices to compare model outputs with field observations and local knowledge, helping build confidence and trust in the results while explicitly communicating uncertainty.
Prof. Tatem emphasised that uncertainty is not a weakness but a vital part of responsible decision-making. In vaccine planning, for example, understanding upper and lower bounds helps ensure sufficient supplies are available to reach all children who need them.
This question sparked a wider discussion among the panel. Ridhi Kashyap and Emilio Zagheni argued that prediction and explanation should not be viewed as competing goals, while Tatem’s presentation highlighted the necessity of explainable models that decision-makers can understand, interrogate and trust.
Both Emilio Zagheni and Matthew Hauer discussed the difficulty of creating synthetic datasets that accurately preserve complex real-world relationships while protecting privacy. They stressed that maintaining the statistical properties of population data remains a significant research challenge.